Cuphead RL
A reinforcement learning agent trained in a custom simulator that beats Cuphead's first boss in the real game, 30 out of 30 fights.
- #Reinforcement Learning
- #PPO
- #Python
- #PyTorch
- #Stable-Baselines3
- #Gymnasium
- #C#
- #BepInEx
- #Sim-to-real
- #Game AI
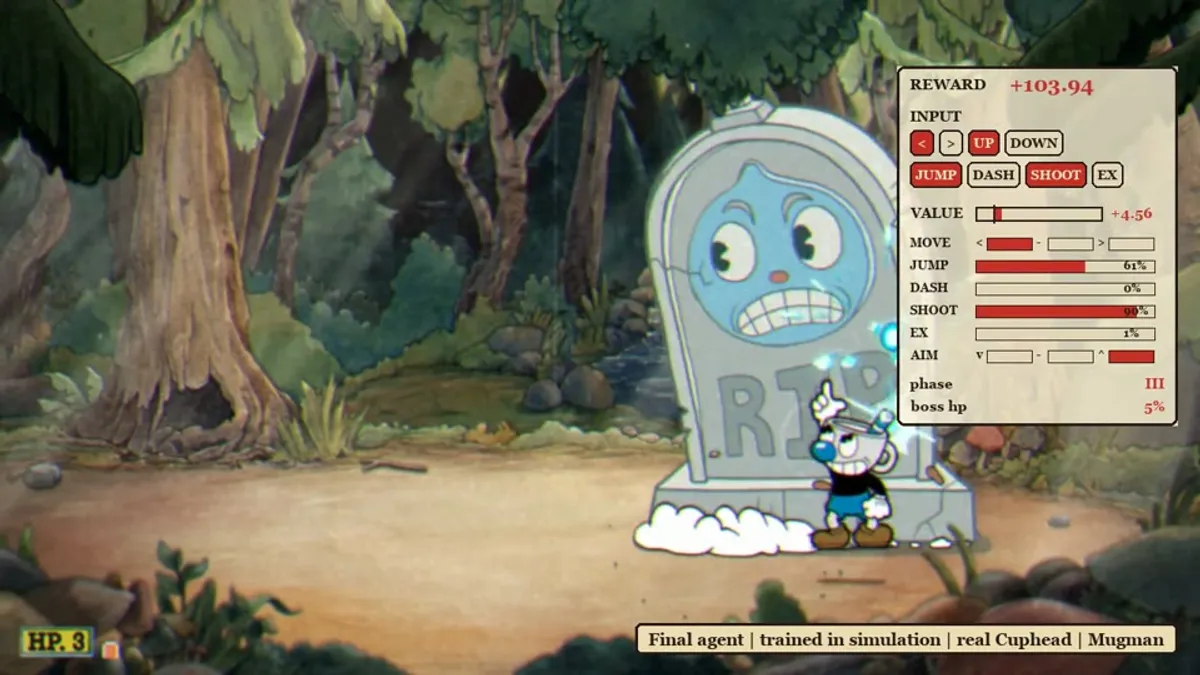
A PPO agent trained entirely in a custom simulator that beats Goopy Le Grande, Cuphead’s first boss, in the real game: 30 fights out of 30. The video covers the whole project, from the simulator to the agent playing the real game.
Why
Cuphead is one of my favourite games, and building an agent that can play short, brutally hard levels like these is one of the reasons I got into reinforcement learning. Training directly in the game is too slow: it runs in real time, and an agent needs millions of attempts. So I built a simulator of the fight.
How it works
- Simulator. A Python simulator of the fight, calibrated against the game’s decompiled code and recordings of the live game. It runs about 400× faster than real time on a CPU.
- Observation and actions. The agent doesn’t see pixels. It gets 142 numbers describing the fight and chooses six actions at once: move, jump, dash, shoot, EX and aim.
- Training. PPO (Stable-Baselines3) with a reverse phase curriculum, which starts at the boss’s last phase and works backwards, and ±15 % randomized physics.
- Game bridge. A C# BepInEx/Harmony mod connects the real game. It reads the fight state, sends it to Python over a local socket and applies the agent’s inputs. The game waits for each decision (lockstep), just like the simulator.
Closing the sim-to-real gap
Most of the progress came from finding where the simulator and the game disagreed, not from a smarter algorithm. A mirrored punch rule in the simulator meant the agent was learning to dodge a boss that doesn’t exist. Logging the cause of every hit in both worlds closed the gap until the simulator predicted the real game: 0.81 vs 0.80 hits per fight.
Results
| Result | |
|---|---|
| Real game | 30/30 wins (20 lockstep evaluation fights and 10 recorded in real time) |
| Real game, lockstep | 0.40 hits per fight; 12 of 20 fights won without taking a hit |
| Simulator | 100 % wins on 100 held-out test fights |
| Training on the real game | None |
Code and details
The repository has the full research log, the code and the trained model.
Fan project for research and education. Not affiliated with Studio MDHR.